Tag: Google

  • Google and Intergalatic Law

    What happens when you open Google Docs in a non-standard browser like Opera Mini? You get the following snippet.

    Sorry, but this browser does not support web word-processing.

    Please see our system requirements page for a list of supported browsers.

    If you are working to fix problems with a specific browser and would like to bypass this check, just add ?browserok=true to the end of the Google Docs url.

    Please note that it is a violation of intergalactic law to use this parameter under false pretenses, so don’t let us catch you at it.

    And, it won’t work very well — really.

  • Sponsored Conversations

    What do you get when you combine speech recognition, contextual advertising, text-to-speech software, and a disruptive business model? A phone that’s free as long as you are willing to listen to advertising.

    Don’t laugh, the idea has been kicked around before. But why stop there? You could link the price of the monthly contract to selected offers. Some other ideas,

    • Use GPS to verify check-ins at certain locations. As long as you’re at that location, long distance calls are free. Mom, I know it’s noisy at this bowling alley but as long as I’m here, this call is free.
    • Use 2D barcodes to redeem mobile coupons that unlock discounts. Buy a Big Mac and get 1000 text messages free.
    • Track coupon history for special offers. Feeling sick after that Big Mac? There’s a gym right down the road from you. Why not stop by for an orientation?

    The mind reels.

  • Fun with Google Text-to-Speech

    UPDATE: Bummer, looks like it no longer works.

    Fooling around with Google Translate and their 100 character Text-to-Speech engine I strung together a few lines from Eric Schmidt’s editorial in The Wall Street Journal.

    Eric Schmidt! WOW! Welcome Google to Argentina! =)
    Image by TheAlieness GiselaGiardino²³ via Flickr

    Click on the following links in order.

    1. One
    2. Two
    3. Three
    4. Four
    5. Five
    Reblog this post [with Zemanta]
  • Fun with Google Social Search

    Google Social Search is now available in Google Labs. Danny Sullivan has the most in-depth coverage out there but it’s worth turning on yourself because you’re going to be the best judge of how well this feature performs for you.

    Be sure to dig deeper than the default two results Google throws timidly down at the bottom of your search results. Click Show Options and click on the Social category in your sidebar. Check out the results you get for People and you’ll get a feel for the power of this feature.

    You have the full index of Google quickly filtered by names that should be familiar to you. In a stroke of genius, Google has re-labeled this extended network your, “social circle” which a much better label than “friends” (which didn’t sound right) or “social graph” which no one really understood.

    The screenshot above is my aha moment – I had no idea that Caterina ever was in Finland and certainly didn’t know that she took the time to blog about suggestions of things to do in Helsinki. This is a post from 2003 which most certainly have been lost to the sands of time if it were not for this feature which surfaced this gem in just a few clicks.

    And now for a feature request. As you can see, this is a great feature for retrospective searches which makes the foggy past plainly visible.  What about adding an RSS subscribe option so that you could apply these searches to the prospective future?

    It would be great to know when any of my extended social circle also wrote about my adopted hometown. I suppose it would be easy enough to script something but why not build it in?

  • Traffic Sources and Attention

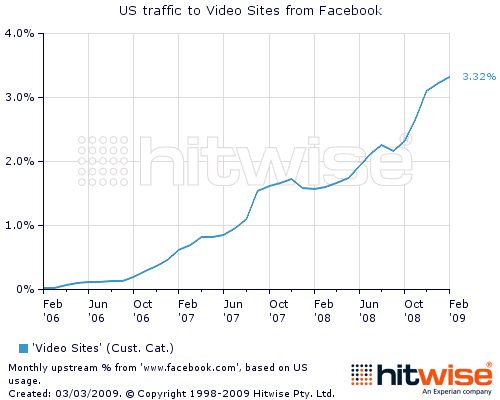
    There’s been good debate around how the source of traffic to sites is changing, shifting from the search engines to social sites such as Facebook and Twitter. I confirmed that I too am seeing a greater percentage of traffic come in via links shared on social sites and shared a colleague’s theory about what this would mean for Google’s advertising revenues. Fred Wilson also posted about this topic here and here.

    What about attention? How does the average visitor from a social site compare to someone from a search engine? Niall Kennedy tweeted the following stats from his referral logs:

    • Twitter: 7 seconds
    • Digg: 20 seconds
    • StumbleUpon: 40 seconds
    • Facebook: 52 seconds
    • Delicious: 82 seconds

    timespent

    Here are my stats for the past year:

    • StumbleUpon: 40 seconds
    • Digg: 42 seconds
    • FriendFeed: 53 seconds
    • Facebook: 60 seconds
    • Twitter: 86 seconds*
    • Delicious: 110 seconds
    • Techmeme: 114
    • MyBlogLog: 176 seconds

    Compared to the attention span of those coming from the major search engines we get:

    • Live.com (MSFT): 21 seconds
    • Yahoo: 35 seconds
    • Google : 40 seconds
    • Ask: 46 seconds

    It would be interesting to see figures from other sites, especially online shopping sites which are the ones most interested in getting (and therefore likely to pay for) traffic. While it’s clear that visitors from social sites are more engaged with my blog because they tend to hang around a bit longer, that may not be the case with a shopping site where there is less intent to purchase than if they come from a search engine but Mark Essel thinks otherwise.

    Increasingly, the flow of web links is being made between individuals via social media sites.  Your good fishing buddy who knows the Bay area, shares a link to his favorite supply store.  As focused communities become populated across geographic barriers, local quality referrals become more likely.  But what if you want to know what store fishermen prefer in San Francisco?  You could simply use twitter search for fishing san francisco.  In real time you could send a message to several individuals who are interested in fishing in that region.

    Shared links are compelling but they need to be matched with impulse buying or discoverable when you’re looking for it. I’m thinking of O’Reilly’s flash discount shared via twitter (44% off to celebrate the 44th president) which was effective in bumping registration at the recent Web 2.0 Expo. The other way to generate business via shared links is to make them searchable so you can find what you need when you want it – but then we’re right back at sending traffic via search again.  Yes, you can search twitter but you can find this stuff on Google too.

    The jury’s still out as I think this will be a slow shift of behavior that will take a long time to impact existing business models. The real prize is back to social search which would combine the best of the recommendation trusts of social networks with the ability to find what you need when you’re looking for it.

    Facebook recommendations married to Google ‘s structure and ranking? That’s the subject of another post.

    —o—

    * I dug into the Twitter figures because they’re so out of whack with what Niall is seeing and it looks like there are a few visitors that hung out for a long time that are pushing that average higher than it should be.

    Reblog this post [with Zemanta]
  • AdSense, Self-Optimized

    google behavioral targeting options

    It’s obvious when you think about it. Instead of spending your energy throwing up hundreds of ads that dance around the edges in the hopes that one will magically trigger a random click of interest, why not ask your readers, “What do you want to see?”

    Google announced a new program which changes the way they pick which Adsense ads appear on the websites you visit. Instead of looking at the content on the page and simple IP-based geo-targeting, the new program looks at your browser history and targets advertising based on your browsing interests. It’s known in the industry as behavioral targeting but Google has re-labeled it “Interest-based advertising.”

    The system works using tracking cookies which is anonymous and tied to your browser so if you switch browsers or jump to another PC, your browsing history will not follow you (although technically it’s possible if they tied the cookies to your Google Account). Likewise, your browsing history is going to get muddled on shared PCs such as one you might find in a family room.

    The most interesting thing about this new program is that they are allowing you to edit your profile using a new Ad Preferences Manager. As you can see in the screenshot above, you can pick and chose from 20 major categories and 600 sub-categories that are interesting to you and begin to shape the type of ads that are served to you. There is an option to opt out completely in which case you’ll get the regular content matched advertisements we’ve been seeing all along but having the ability to customize what you see is a bold step forward in transparency.

    Arguments against such a system when I had brought it up in the past were that if you let everyone pick and chose your ads you run the risk of not serving a well-balanced mix of advertising, running dry in popular categories and having a glut of units from less popular categories. By putting direct user feedback into the equation, you could no longer tune your ad servers to optimize for maximum profit.

    My counter to that argument is that by putting your readers in charge of what they see, you stand a much better chance of not only having people look at your ads (to see what type of ads get served) but also getting a much better sense of what interests your readers.

    So here’s my crazy idea. Why not go a step further? Why not let people to search for ads directly? Every magazine has an Advertiser’s Index in the back, why isn’t there a web-based equivalent? It’s been done.

    For more detail and commentary, Barry Schwartz has an extensive write-up on this development over on Search Engine Land.

  • Facebook, Twitter send more traffic than Google

    Facebook, Twitter send more traffic than Google

    Liz Gannes posted that Perez Hilton is now seeing more traffic coming in via Facebook than Google.

    My colleague Udo Szabo at Nokia HQ in Finland has a theory that I call the Unified Theory of Interweb Economics. The theory goes something like this:

    1. Advertising is a function of your traffic volume, the more traffic that comes to your site, the higher rates you can charge.
    2. Social sites such as Facebook and Twitter have a lot of link sharing going on as friends post links to share them with each other.
    3. When Facebook and Twitter send more traffic than Google search referrals, advertising dollars will follow the source of that traffic.
    4. Google’s dominance in online advertising will be threatened.

    One would think we’re seeing the first hints of that with perezhilton.com and it will take a long time before we see this trend across the board. But in hindsight this is obvious and looking at my stats for the past month I find that 44% of my visitors are coming from search engines and 45% from referring sites with a vast majority coming from StumbleUpon, a social site for sharing links.

    The more you think about it, the shift in balance of power has already taken place.  SEO is still a big industry but now there are companies that will help you with SMO (“social media optimization”).  On twitter we’re starting to see scam artists try and insert themselves into the conversation just as they used to do with Splogs.

    And so the wheel turns round once again and there appears to be a new king of the hill – AOL Keyword > Yahoo Category Link  > Google Keyword Ranking > Social Site referral.

    The jury’s still out as to which social site will send you more links but it’s looking more and more like Facebook. We used to have the Digg effect but no one talks about that anymore. Twitter certainly has the ability to send you a bunch of traffic in short order but the audience is still mostly the early-adopter set and any traffic will most likely be short-lived as the re-tweets scroll into the past.

    Facebook, with 175 million users, certainly has the right broad-based distribution to broadcast a link and send back traffic. They have added new features such as FriendFeed’s “like” feature to make quick sharing easy. The Facebook Connect and Comments widgets also will help insert new links into Facebook for redistribution.

    But while it’s great to get an influx of new visitors via a social site, it’s no good if it’s not a lasting reference. Has the pendulum swung to far the other way? There are some searches that work great on the real-time web, the latest viral video comes to mind, but others such as the listing for your local plumber just don’t work on something like twitter. Not that it’s worth anything but I still get a regular influx of traffic because I’m the #2 listing for insulting british slang even though the post is over three years old.

    I think it’s fair to say that the social sites such as Facebook and Twitter will erode Google’s monopoly on online advertising. Google’s never been really good at building social sites and have shared in the growth of social networking in the past by providing the advertising engine for the most popular social sites. What happens with these sites start to go direct to the advertisers? Will Facebook advertising revenues come from traditional cost-per-click/auction model or is some other type of model required to succeed in a social networking site?

  • Do Social Gestures a Business Model Make?

    Is twitter a directory or a utility? This is the question that Charles Hudson raises in his post The Database of Intentions is More Valuable than the Database of Musings. While investigating prospective business models, he raises good questions about the ability of a collection of “accumulated musings” to determine intent which is what is most valuable to advertisers.

    But maybe advertising  is not the great revenue driver of the next generation of startups after all, at least not advertising as we know it. Maybe it’s just me but I feel a need to make sense of all the stuff we share with each other. There seems to be value in tapping into the pulse of the “now web” but the methods of pulling meaning out of the noise seem crude. Keyword searches? Is that the best we can do?

    Something went wrong with the Intense Debate comments on last night’s post on Keywords and Meaning. It’s unfortunate because there were some really thoughtful responses to the post which I’ll repeat in this post because they are worth reading.

    Todd writes:

    Keyword extraction from Twitter could be cool, but may kill of serendipitous discovery, my favorite aspect of Twitter. If keywords or meta-categories are predetermined truly unique hawtness, unprecedented new things ( a Twitter specialty ) will just get deleted? That would be FAIL.

    I wonder if more of a “people with attributes” are really what’s needed. Example, I do want to know what’s going on with the latest developments for Symbian operating system, particularly activity streams and address book stuff. Rather than rely on keyword extraction, I could just assign an attribute to your tweets…

    twitteruser:iankennedy=novi

    …I can be fairly assured news filtered by real humans, THEN assigned an attribute of my choosing will bring me some good results. A tag cloud of all tweets containing “symbian, activity stream, address book” would be noisy ( pollute with people asking each other for tech support? ), difficult to pull meaning from while drinking beer at my favorite bar.

    Jonathan Strauss writes:

    The TechCrunch post you cite was inspired by John Borthwick’s very interesting essay on how Google’s approach to content filtering breaks in the realm of what he calls the ‘Now Web.’ Like you say above: “Google’s PageRank, while valueable in sorting out the reputation and tossing the hucksters, is no good when applied to real-time news which is too fresh to build up a linkmap.”

    In the (relatively) static web, the network nodes are pages and the endorsement actions are the links between them which are effectively permanent as well as public, and thus crawlable. In the Now Web, the network nodes are people and the endorsements are ephemeral share actions, the majority of which are not public or crawlable (i.e. email, IM, Facebook — what I call the ‘Deep Now Web’). And so, authority also takes on a different form from the aggregate view that PageRank provides to the personal measure of how much influence an individual has with her social network on a particular topic at a given moment.

    I agree that we need to have a means of systematically capturing the newly important metadata of share actions and that it needs to be done at the point of sharing (see Jeff Jonas). But, I believe the more easily adopted (and thus ultimately more useful) taxonomy will be one of contextual metadata (i.e. who/what/when/where/why/how) rather than the more personal folksonomy/tagging approach you suggest.

    There was also reactions via twitter from Kevin Marks:

    https://twitter.com/kevinmarks/status/1213846940

    The act of sharing links, photos, or other metadata on social networks is an action, to a certain extent, that gesture is more interesting than the actual data itself. The fact that my usually dormant cycle racing friends are now extremely active on twitter these past few days as the Tour of California is on is as much an indicator of interest as the actual substance of their conversation.

    Keywords are part of the picture – the complete context around who/when/where/why/how are just as important as the tidbit of data itself. The meta-data contains more clues than the data.

    The cellphone is a rich source of meta-data which can be captured at the source, the moment of sharing. Feeding contexts captured from the cell phone would be a great way to add context to any act of sharing.  There are privacy concerns and ownership questions. There needs to be a real value demonstrated to the potential user before they give up some of this privacy. But that’s a topic for another post.

  • Keywords and Meaning

    Keywords and Meaning

    TechCrunch asks if twitter search gets us closer to being able to mine the world’s collective thoughts. We may be getting there as millions text their latest thoughts into their cellphones. With a simple text message, the hive mind has the potential for 4 billion nodes out in the real world (for comparison, the human brain has 100 billion neurons)

    News junkies of the world turn to twitter as the latest source of raw, unfiltered information. Peering over the shoulder of various members of the House and Senate who twitter is a unique view into our government. What you see is a more intimate, human view of the people that make the news. Yet, how do you harness that noise and turn it’s output into information?

    Twitter follows a long line of services which break through editorial filters, get at the source of a story so you can make your own judgements. Blogs occupied this space just a few years ago and real-time indexes such as Technorati rose to prominence as a way to get a jump on the news.

    Sidenote: Alacra, admitting important news about companies breaks on the web, is launching Pulse which applies their analytics engine to extract company names from their hand-picked collection of 2,000 RSS feeds.

    The need for speed is nothing new. Former Wall Street Journal newsman Craig Forman draws an arc that extends from the pigeons Baron Reuter used to deliver news of  Napoleon’s defeat at Waterloo to the real-time newswires used in the financial world today . If there’s a way for someone to profit from the knowing something before anyone else, there’s always going to be people looking for a way to get at a scoop and others looking for a way to deliver.

    We want to look to twitter for the scoops but we are doomed to learn the same lessons as we have in the past about authenticity. What we gain in speed and convenience, we lose in validation and measured fact-checking. Google’s PageRank, while valueable in sorting out the reputation and tossing the hucksters, is no good when applied to real-time news which is too fresh to build up a linkmap.

    Working for Dow Jones in Tokyo, I would work with bankers and reporters who would use digital newswires to deliver them the latest news from around the world. As a systems engineer setting up their workstations, I would often be asked to set up their news filters to narrow the feeds down to something reasonable (the typical newswire delivers hundreds of stories an hour, most subsribe to several newswires). In the late-90’s the tools were crude and after getting frustrated by throwing in a few keywords, I would get called in to refine things using additional tools such as company ticker symbols, or a few undocumented codes from a taxonomy of subjects that varied from newswire to newswire.

    Today the problem of information overload has spread to the greater population trying to derive value from the rushing torrent of updates coming out of twitter and facebook. How do I manage all this stuff and figure out what’s important? We use the tools we have but if you think about it, Google Trends and twitter search are just keyword searches with very crude resolution. We have a long way to go before such tools will let us tap into the collective mind.

    Perhaps it’s time for a crude taxonomy for social networks to help sort out the types of messages flowing back and forth? Imagine if all your tweets, facebook messages, and friendfeed streams came pre-tagged with the following tags or categories?

    • look at me, I’m doing something cool
    • check this out, it’s funny
    • books, movies, music, food, or sports
    • this is touching and will change your life
    • gadgets and meta, technology post about using technology
    • weather and the natural world
    • babies and kittens
    • my obscure hobby
    • breaking news, OMG!
    • make money now!

    What other categories would you add? Librarians of the world, what keywords would you put into your search filters to help grep out what goes where? Categorization is the first step towards ranking and with ranking you get useful filters.